- bf16
- 55.6 GB
- Q8_0
- 29.0 GB
- Q4_K_M
- 16.8 GB
- MLX 8-bit
- 28.6 GB
- Q8 agrees
- 259 of 260
Public Jeb · local decision models
A probability. For every answer.
Give Jeb a question and the allowed answers. It scores each answer, so your app can choose what happens next. The 27B is a LoRA fine-tune of Qwen3.8-27B; the board result uses the T1e inference recipe.
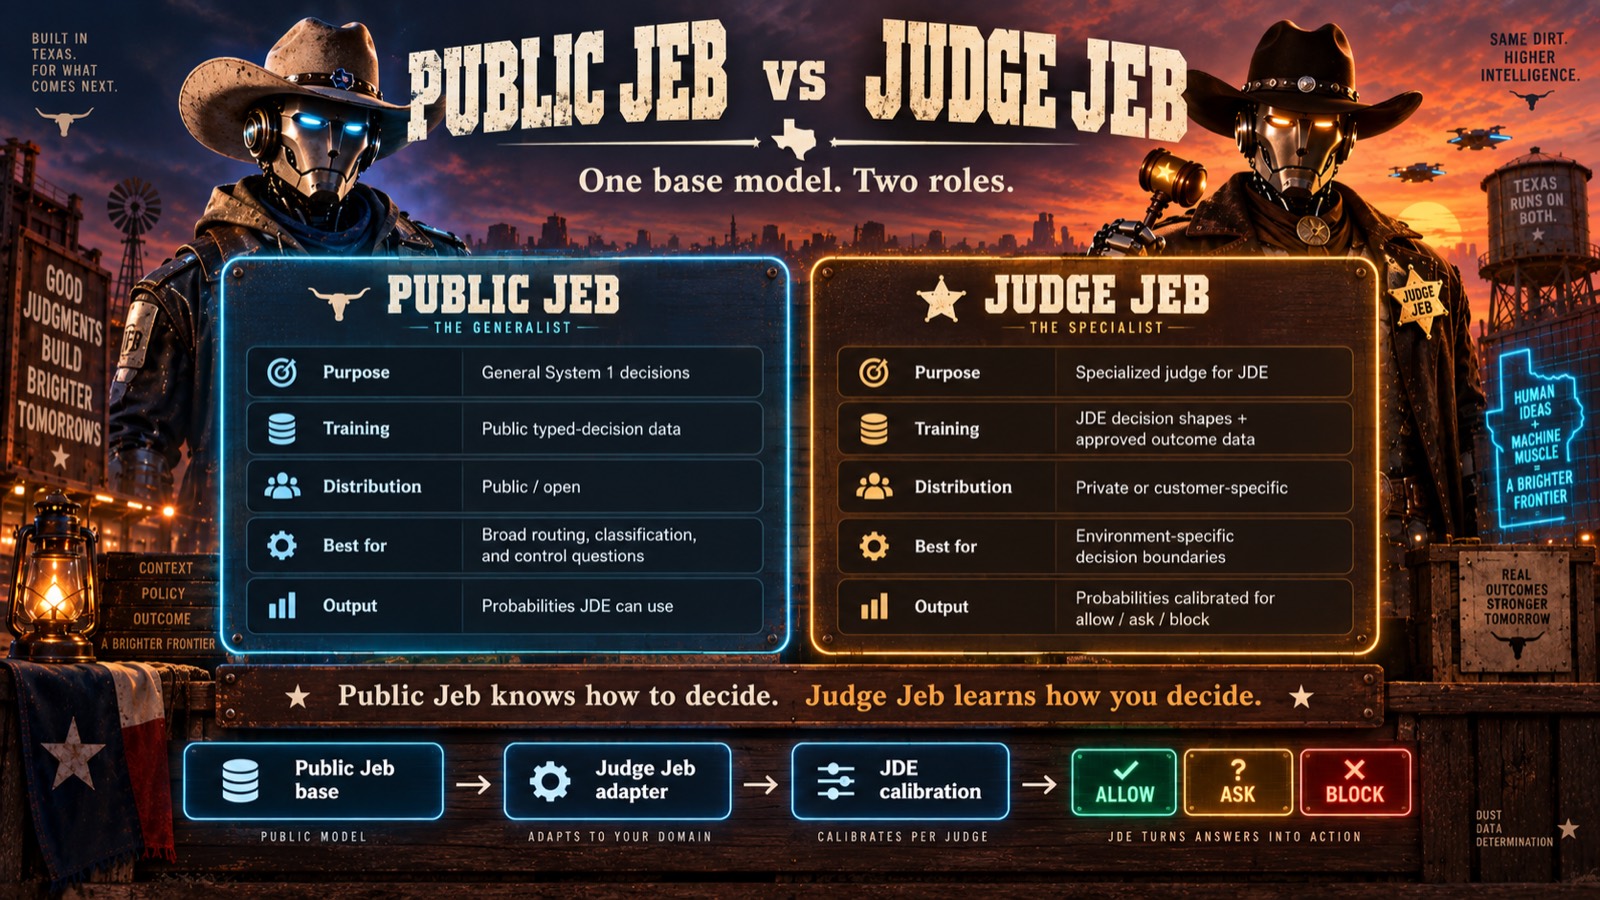
Swipe for Judge Jeb →
On this page, as on the posters: solid frames exist today, dashed frames are work in progress.
Observe → Measure → Calibrate → Trust → Automate
News · October 22, 2026
Latest results on Decision Index 0.4.1.
Jebadiah 27B v2.1 with the T1e inference recipe scores 64.4: rank 25 overall and tie rank 6. The Jev 1.14 reference scores 60.24, rank 41 overall and tie rank 10.
These are the independent board's Full scores from its October 22 data, across 226 ranked rows, including the Jev reference. The board combines private tests of the same skills and private tasks from new domains, mapped to a common scale. A score is not a percent-accuracy claim, and a tie group is not the overall position.
The smaller 9B v2.1 with T1e scores Full 50.9, rank 80 overall and tie rank 18. Its board median latency is 125.1 ms, compared with 303.2 ms for the 27B. These are timings from the board reproductions on one RTX PRO 6000, not a speed promise for another setup.
The entry is a LoRA fine-tune, not a foundation model trained from scratch. T1e is a way of running the checkpoint. The result does not describe an ordinary chat session or every quantized build.
The board describes both entries as the same published v2.1 weights with a new inference recipe. The 9B is a LoRA fine-tune of Qwen3.5-9B. In the lab's check against the submitted decisions, agreement was 100.00% for the 9B and 99.90% for the 27B, each on 831 rows. Both answered all 110,201 requests. This checks reproduction of submitted answers, not task accuracy.
What Jeb does
He doesn’t talk much. He just decides.
A support desk gets a ticket. It needs four answers before anyone reads it: which team, whether to reply today, how upset the customer is, and whether they want money back. Here is what Jebadiah 9B v2 returned on our fleet on 26 September 2026.
Incoming ticket
“Payouts failing again. Third payout this week bounced with error PAYOUT_REJECTED. I have to pay two contractors by Friday and your status page says everything is fine. What is going on?”Unassigned
Jeb 9B v2 · four questions
about 1.3 s end to end
Which team takes it?
choiceReply today?
noulHow frustrated is the customer?
scoreExpected level 2.29 on a 0 to 3 scale: between frustrated and angry.
Is the customer asking for a refund?
noulWhat a chat model gives you
“This sounds like a billing issue, though it could involve the technical team since there's an error code. The customer seems quite frustrated, so it would be good to respond promptly...”
Now write code that turns that into a route, a priority and a refund flag. Then do it again when the wording changes.
What Jeb gives you
Numbers your code can use as they are. Route to billing because 0.878 clears your bar. Page someone because frustration sits at 2.29. Skip the refund flow at 0.020. The same question asked twice gets the same numbers.
choicePick one of several named options. Jeb returns a probability for each.
noulA yes or no statement. Jeb returns the probability that it is true, from 0 to 1.
scoreAn ordered scale. Jeb returns a probability per level and the expected level.
Public Jeb · the generalist
Three sizes. Open weights.
Every model is Apache-2.0 and trained on public data only. The 27B and 9B scores below are independent Decision Index 0.4.1 Full results with the T1e inference recipe. The 4B uses our internal evaluation on a different public test set it never trained on. The 4B is not on the Decision Index; its internal evaluation is not directly comparable to the Full scores.
- bf16
- 19.3 GB
- Q8_0
- 9.8 GB
- Q4_K_M
- 5.8 GB
- MLX 8-bit
- 9.5 GB
- Q8 agrees
- 257 of 260
- Q8_0
- 4.6 GB
- Q8 agrees
- 256 of 260
v2.1 scores: The board describes both T1e entries as the same published v2.1 weights with a new inference recipe. Our submitted public runs score 60.46 (27B) and 51.53 (9B); these public scores are separate from the private-test Full scores. Every request and score from the submitted public runs: 27B T1e run and 9B T1e run. Submitted to the board: 27B #199 and 9B #188. On a Mac, take the MLX 8-bit; the 9B 4-bit is the bare minimum.
On Decision Index 0.4.1: 27B v2.1 with T1e scores Full 64.4, rank 25 overall and tie rank 6; 9B v2.1 with T1e scores Full 50.9, rank 80 overall and tie rank 18, with 125.1 ms median latency in the board setup. Board data 2026-10-22. Details.
JevBench: on its 231 public items, run through its own harness, Jebadiah 27B scores 0.866, the same as Jev 1.13.0. Our run, not the official board. Details and caveats.
“Q8 agrees” is how often the 8-bit GGUF gives the same answer as the full weights on 260 held-out questions. Smaller downloads, same decisions.
All three live in one Hugging Face collection, with mirrors on ModelScope.
Run it anywhere
Your hardware. Your call.
One command: jeb serve
Install the jeb command and start it in front of the runtime you already have. It serves decisions on http://localhost:8100: POST /v1/systemone speaks Jev's wire format: JDE judges there by default with no key and no config, and an existing Jev client works once you change the endpoint. POST /v1/decide takes AINode's shape.
Python 3.10 or newer. No torch, no transformers. On the Ollama path, a clean setup answered its first decision in 2 minutes 1 second, most of it the model download.
pip install jebadiah-decide
jeb serve     # Ollama: pulls the 9B Q8_0 (9.8 GB) the first time
jeb doctor    # checks the runtime, the model and a known answer

# decisions   POST http://localhost:8100/v1/systemone
# also        POST http://localhost:8100/v1/decide
Ollama or LM Studio
The fastest start. jeb serve pulls the model into Ollama and serves it. For LM Studio, load jebadiah-9b-v2 Q8_0, switch its server on, then run jeb serve --backend lmstudio. Up to 20 options per question on both.
llama.cpp or vLLM
Run llama-server on the Q8_0 GGUF, then jeb serve --backend llama-server, with no limit on options. Or serve the full weights with vLLM and run jeb serve --backend vllm.
MLX on a Mac
No other runtime needed. jeb serve --backend mlx downloads the 9B v2.1 from jebadiah-9b-v2-1-MLX-8bit the first time, with no limit on options.
AINode
An open-source local AI platform for NVIDIA GPUs. It serves Jeb on vLLM and answers /v1/systemone and /v1/decide itself, across a cluster. AINode path · github.com/getainode/ainode
A note on chat apps
Don't judge Jeb in a chat window. Every runtime's chat runs with thinking on and shows text, and Jeb isn't built to write text, so what you see there is nonsense by design. A decision reads the probability of each answer, which is what jeb does.
GGUF builds, including third-party ones, may show a “Vision” tag in LM Studio because the Qwen base has a vision tower. Jebadiah is not trained on images, and the file isn't needed.
Advanced: without jeb
Each model repository still carries one script per runtime (scripts/decide_gguf.py, decide_ollama.py, decide_lmstudio.py, decide_mlx.py) for a single request file, and the repository has a standalone server that runs the full weights with PyTorch: uv run jebadiah-serve --model frontier-infra/jebadiah-4b-v2.
Judge Jeb + JDE
Public Jeb knows how to decide. Judge Jeb learns how you decide.

In training
Judge Jeb
- An adapter on the same Jeb base
- Trained on JDE's decision shapes and approved outcomes
- Private when it is trained on a customer's data
Its first training data comes from JDE's own ledger: decisions recorded in shadow mode, then labeled by what actually happened.
Open source · MIT
JDE, the Jeb Decision Engine
Jeb is the model. JDE asks the question and turns the answer into allow, ask or block.
- Judges. Several models can answer the same question.
- Per-judge calibration. Each judge's numbers are fitted so 0.8 means 0.8.
- Bands. Every answer lands in allow, ask or block.
- Ledger. Every decision and its outcome, kept.
ALLOWMove forward
ASKGet clarity
BLOCKPrevent risk

Coding-agent hooks
“All tests pass.” Did they?
In design · shadow mode firstA coding agent finishes and says it is done. A distiller reads the session and reduces it to one question with the evidence attached. Jeb answers. JDE puts the answer in a band.
RequestFix the login timeout, add a test.
ClaimAll tests pass.
EvidenceRan
pytest tests/test_login.py → 1 passedQuestionnoul “The evidence supports every part of the claim.”
Jeb's answer
0.34
00.51
ALLOW
ASK
BLOCK
One test file ran. “All tests” is a bigger claim than that, so the agent gets asked, not waved through. Where the band edges sit is set per judge by calibration.
Agent session→Distiller→One question→Jeb→Band
DecisionBench
Measure the judge where it works.
ComingLeaderboards score a model alone. DecisionBench scores a judge inside an engine, the way it will be used, and runs the same way on every model. The code and data will be public.
Threshold error
How often it acts above the line when it should not have.
Recalibration cost
How many labels it takes to recalibrate.
Flips
Whether the same question gets a different answer.
Noise
How much the numbers wobble between runs.
Speed
Time per decision.
Cost
What each decision costs to run.
Where Jebadiah is
Same dirt. Higher intelligence.
Three kinds of evidence, strongest first: what someone else measured, what we measured that you can rerun, and who has picked Jeb up. Current board numbers are from 2026-10-22; earlier results are kept as dated history.
1 · Measured by someone else
Decision Index 0.4.1 · independent board · data generated 2026-10-22 05:40:06 UTC
Full 64.4. Rank 25 overall and tie rank 6.
The board entries are Jebadiah 27B v2.1 (t1e), a LoRA fine-tune of Qwen3.8-27B, and 9B v2.1 (t1e), a LoRA fine-tune of Qwen3.5-9B. Both use the same published v2.1 weights with a new inference recipe, per the board notes. The Jev 1.14 reference scores 60.24, rank 41 overall and tie rank 10.
The Full score is 60% private tests of the same skills and 40% private tasks from new domains, both mapped to the public scale using 21 untuned stock models. The board uses a 0.9-point tie band; tie rank 6 names a group, while rank 25 is the overall position.
For this entry, public benchmarks score 60.46, shown but not counted in Full. Private same-skills and new-domain tasks map to 58.98 and 72.52 on the public scale. These are benchmark scores, not accuracy percentages. The 9B T1e entry scores Full 50.9, rank 80 overall and tie rank 18. Its public score is 51.53; private same-skills and new-domain tasks map to 50.57 and 51.39 on the public scale.
The board reports median latencies of 303.2 ms for the 27B entry and 125.1 ms for the 9B entry. Local reproductions use one RTX PRO 6000. This is benchmark timing, not a promise for another machine; the hosted Jev reference includes network and service scheduling, so its latency is not directly comparable.
| Entry | Full | Overall rank | Tie rank |
|---|---|---|---|
| Jebadiah 27B v2.1 · T1e | 64.4 | 25 | 6 |
| Jev 1.14 reference | 60.24 | 41 | 10 |
| Jebadiah 9B v2.1 · T1e | 50.9 | 80 | 18 |
Earlier board snapshots, with their original dates
Historical Decision Index 0.4.1 snapshot · October 21, 2026
The board data generated 2026-10-21T22:34:35Z listed 27B Full 64.4 at rank 25 overall and tie rank 5, and 9B Full 50.9 at rank 79 overall and tie rank 17, across 223 entrants plus the Jev reference. Full scores are unchanged in the newer snapshot above; positions and tie groups can change as the board adds entries.
Historical Decision Index 0.4 snapshot · October 20, 2026
The earlier board snapshot listed 27B v2.1 with T1e at Full 65.37, rank 14 overall and tie rank 5; 9B at 50.53, rank 69 overall and tie rank 17; and Jev 1.14 at 62.22, rank 28 overall and tie rank 8. Its 27B new-domain mapped score was 74.95. These are historical figures, superseded by the dated 0.4.1 results above.
The 4B's earlier 72.5 was our internal evaluation on a different test set, never a Decision Index result and never comparable to the board's Full scores.
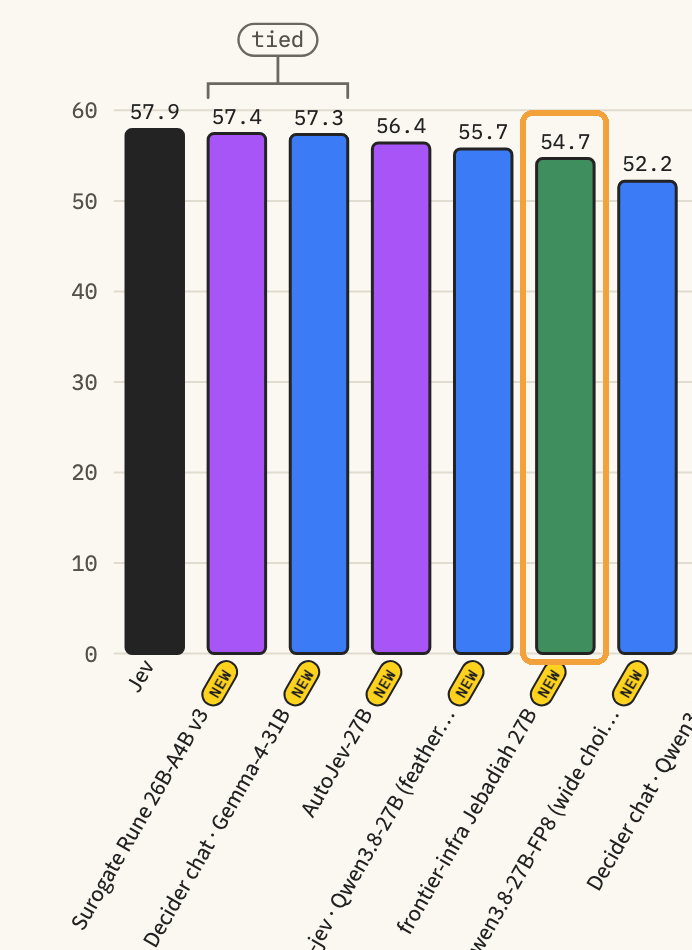
Decision Index v0.3.1 · the board's own numbers · generated 2026-10-10
Published Jebadiah 27B (v2) is #11 (tied) of 117 on Decision Index v0.3.1, with a full score of 55.6 (public 55.1, same-skills 55.2, new domains 56.7).
These are the board's equated scores, from its data generated 2026-10-10 07:54 UTC. Models within 0.9 points count as tied. At that time, Jeb v2.1 was not on the board: our own run on the public items gives 57.03 for the 27B and 47.20 for the 9B, and the official rerun was pending.
History: on Index 0.2.1 (September 26) the 27B was #5 of 67 open models at 54.67, the board's validated number at the time.
On the 0.2 kit, with the kit's own scorer, it scored 50.32. All 151,476 requests were answered (151,034 of 151,034 scoreable). We ran it on one RTX PRO 6000 through the kit's hf-job, at the maintainer's invitation. Median latency was 110.6 ms per request. On 0.2, against AutoJev-27B, it led on retrieval (45.5 vs 42.0) and trailed slightly on knowledge, language, tools and arts.
| Entry | Full score |
|---|---|
| Perplexity Decider v1.1 (27B) | 62.75 |
| Fastino GLiDE no-thinking (28B) | 60.21 |
| Jev | 60.11 |
| Torchcast Decision 27B | 59.91 |
| deck31b (Gemma 4 31B) | 59.03 |
| Kev 27B | 58.78 |
| Quyet-1.0-Large | 58.71 |
| Blink v0.3 26B-A4B (NVFP4) | 57.76 |
| Decider chat · Gemma-4-31B | 57.62 |
| Surogate Rune 26B-A4B v3 | 57.43 |
| Jebadiah 27B (v2), #11 tied | 55.63 |
2 · Measured by us, reproducible
JevBench v1.4.2 · our run · as of 2026-09-26
On JevBench's 231 public items, run through its own harness, Jebadiah 27B scores 0.866, the same as Jev 1.13.0.
Jebadiah 9B v2 scores 0.818 on the same items.
This is our own run on the public items. The board's official ranking also uses sealed items that only its maintainer runs. The 27B's hard-tier calibration (ECE 0.113) is weaker than the 9B's, and it got 4 of 15 temporal and numeric items right.
| Tier | Jebadiah 27B | Jev 1.13.0 |
|---|---|---|
| Easy | 48/48 | 48/48 |
| Standard | 70/72 | 71/72 |
| Hard | 82/111 | 81/111 |
| Score | 0.866 200/231 | 0.866 200/231 |
JDE blind test · as of 2026-09-26
Titanium Computing's production decision engine (JDE): 290 real decisions, blind to training.
Jebadiah 9B v2 against Jev on the same 290 decisions, inside the engine that makes them. JDE is open source.
0 flips
Across 5,800 calls, no answer changed on a repeat. The probabilities were identical from run to run.
277/290
Jeb 9B v2's total, against Jev's 282. Close, and Jev still leads on coverage checks (3 misses to Jeb's 7).
37 vs 35
Jeb beat Jev on the added-requirement checks: 37 of 40 right, to Jev's 35.
3 · Adopted by others
- mradermacher GGUF quantsIndependent GGUF builds of the 9B v2, made by a third party.as of 2026-09-26
- yibie awesome-jevListed in yibie's awesome-jev, the main Jev community list.as of 2026-09-27
- Decision Index news feedListed in the Decision Index news feed, under trained models.as of 2026-09-26
- OmniJev awesome-jev-galleryListed; the pull request is merged.as of 2026-09-26
- logicrw Awesome Jev catalogListed. A catalog entry, not a performance validation.as of 2026-09-26
- LM Studio model searchJebadiah shows up in LM Studio's built-in model search.as of 2026-09-26
- OllayaThe maintainer invited a pull request for the Jeb family.as of 2026-09-26
- Qwen3.5-9B model treeJebadiah 9B v2 appears as a fine-tune in the base model's tree on Hugging Face.as of 2026-09-26
- ModelScopeMirrored: all nine repos (three sizes, each as weights, GGUF and MLX).as of 2026-09-26
- Awesome-LLMOpsJebadiah is listed under Model > Large Language Model.as of 2026-10-07
About the “Vision” tag: GGUF builds, including third-party ones, may show a Vision tag in LM Studio because the Qwen base model has a vision tower. Jebadiah is not trained on images and does not make decisions in a chat window. Use the decide scripts: scripts/decide_gguf.py or scripts/decide_lmstudio.py.
Who builds it
Built in Texas. For what comes next.
Jason Brashear
Builds and trains the Jeb models, and builds AINode.
Frontier Infra
The Hugging Face organization that publishes the weights.
AINode
The open-source local AI platform that serves Jeb on our own GPUs. github.com/getainode